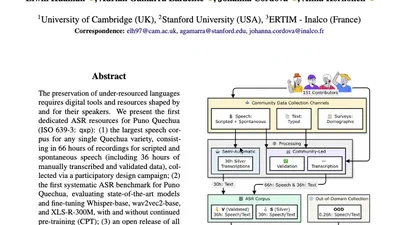
Building Community-Centred NLP Resources for Puno Quechua
We present the largest speech corpus for a single Quechua variety, collected with the community, and the first ASR benchmark for Puno Quechua.

We present the largest speech corpus for a single Quechua variety, collected with the community, and the first ASR benchmark for Puno Quechua.
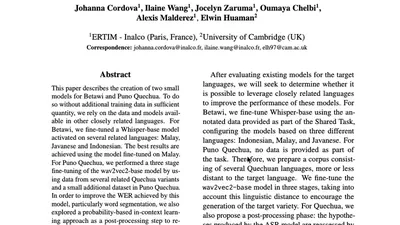
We build small ASR models for Betawi and Puno Quechua by transferring from closely related languages.
The goal of this shared task is to promote the development of robust automatic speech recognition (ASR) systems for spontaneous speech in a number of lower-resource languages that …
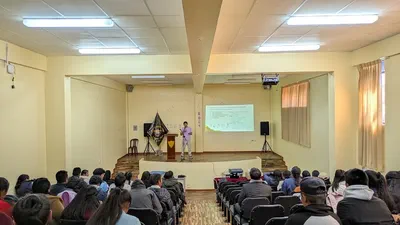
We successfully developed a pipeline to ingest and standardize Quechua linguistic data into Wikidata. The integration of Quechua into the Common Voice platform has yielded …
SIMBig is one of the first conferences in Latin America grouping areas such as Artificial Intelligence, Machine Learning, Deep Learning, Healthcare Informatics, Natural Language …
We detail the integration of the Quechua language family into Common Voice, an open-source initiative to build diverse speech datasets.
This workshop covers how to use the Content Translation tool to quickly translate Wikipedia entries. The practical activities include configuring participants' user accounts to …
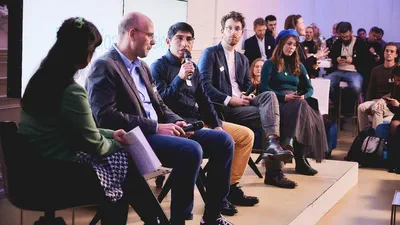
Elwin Huaman, representing the University of Innsbruck, was a featured expert at the netidee Talk 2024. His participation was centered on the discussion on how internet …
We bring the Quechua language into Wikidata. We outline a technical pipeline for data curation and deployment, transforming Quechua linguistic resources into structured, …
In this webinar from the Endangered Languages Project, Elwin Huaman provides a comprehensive introduction to ELAN (Eudico Linguistic Annotator) and VLC Media Player for …